
2026-09-02
How to call DeepSeek V4, GLM-5.3, and Kimi K3 with an OpenAI-compatible API from LatAm
If your stack already speaks Chat Completions, you do not need a separate SDK for every Chinese lab. DeepSeek, Z.ai (GLM), and Moonshot (Kimi) document OpenAI-compatible endpoints. NexoRouter exposes the same contract at https://api.nexorouter.com/v1: change base_url, the API key, and the published ID on the catalog.
This post summarizes facts from official announcements (July–August 2026). For prices, it only quotes strings that nexorouter.com/models showed on 2 September 2026. We do not paste long WeChat or vendor article text.
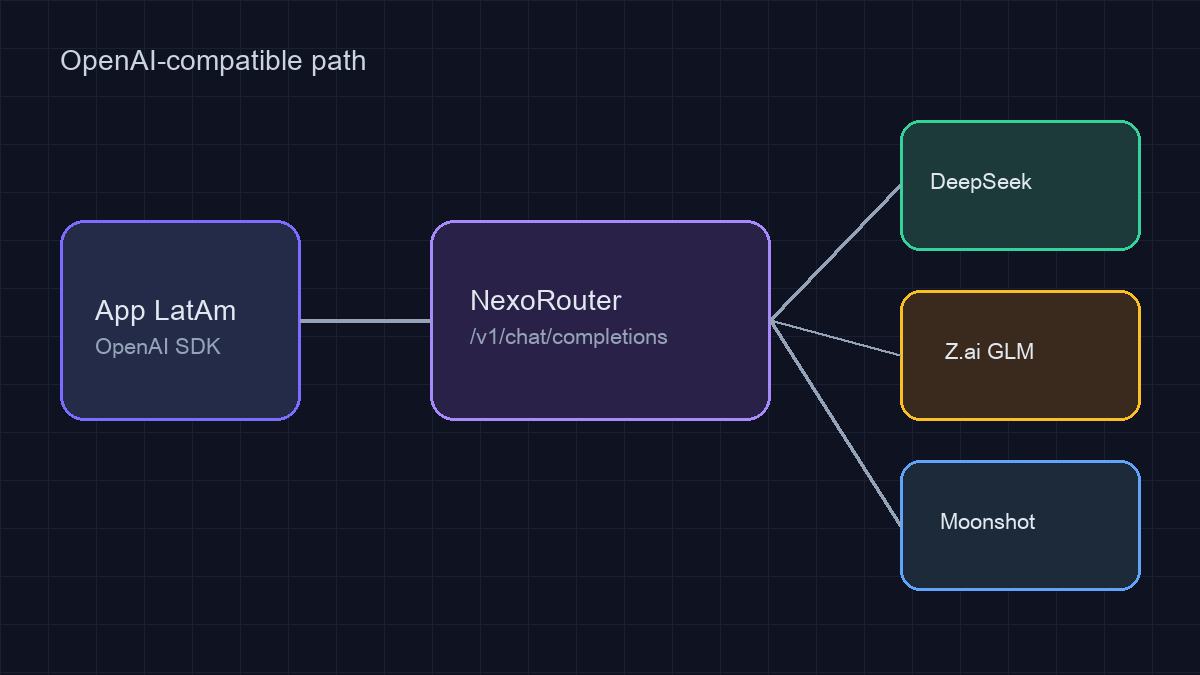
What the vendors announced (official sources)
DeepSeek V4 and the API changelog
On 24 April 2026 DeepSeek published DeepSeek-V4 Preview: deepseek-v4-pro (1.6T / 49B active) and deepseek-v4-flash (284B / 13B active), 1M context by default, plus OpenAI Chat Completions and Anthropic interfaces. The API changelog on 13 August 2026 marks V4-Pro GA; 21 August adds experimental deepseek-v4-flash-vision-exp. Legacy IDs deepseek-chat / deepseek-reasoner were retired after 24 July 2026.
Z.ai GLM-5.3
On 14 August 2026 Z.ai published GLM-5.3: Frontier Coding with Emergent Cyber Capabilities. Same base as GLM-5.2; gains come from post-training. The API requires thinking enabled and reasoning_effort of low / high / max (disabled thinking is no longer supported).
Moonshot Kimi K3
Moonshot presents Kimi K3 on moonshot.ai (research dated 16 July 2026): 2.8T parameters, native multimodal, 1M context. The official Kimi K3 Quickstart sets model ID kimi-k3, reasoning_effort, and an OpenAI-compatible base_url. The model list states kimi-k2.5 and moonshot-v1 retired on 31 August 2026.
IDs and prices on the NexoRouter catalog (2 Sep 2026)
Copy the ID from Models, not from memory. Live strings that day:
| Catalog ID | Input / generation | Cached input | Output |
| --- | --- | --- | --- |
| kimi-k3 | $3.04 / 1M tokens | $0.30 / 1M tokens | $15.20 / 1M tokens |
| glm-5.3 | $1.22 / 1M tokens | $0.30 / 1M tokens | $4.26 / 1M tokens |
| glm-5.3-flash | $0.12 / 1M tokens | $0.03 / 1M tokens | $0.43 / 1M tokens |
| deepseek-v4-flash-0731 | $0.24 / 1M tokens | $0.05 / 1M tokens | $0.49 / 1M tokens |
| deepseek-v4-pro-sg | $2.73 / 1M tokens | $0.23 / 1M tokens | $5.47 / 1M tokens |
If an ID shows Pending, do not invent a rate: wait for a published string or smoke-test in Playground first.
Current NexoRouter model pages (verify prices on the live card)
Compare current model prices and integration examples on these catalog pages. Do not budget from this article — open each model page and read the live pricing panel.
| Exact API ID | Canonical path (EN) | Notes |
| --- | --- | --- |
| deepseek-v4-pro-0813 | /en/models/deepseek/deepseek-v4-pro-0813 | Dated Pro catalog ID |
| deepseek-v4-flash-0731 | /en/models/deepseek/deepseek-v4-flash-0731 | Dated Flash catalog ID; live panel may differ from the 2026-09-02 snapshot row above |
| kimi-k3 | /en/models/moonshot-ai/kimi-k3 | Flagship Moonshot mapping |
| glm-5.1 | /en/models/zhipu-ai/glm-5.1 | Distinct from glm-5.3 announcement SKU |
| qwen3.6-plus | /en/models/alibaba-cloud/qwen3.6-plus | Alibaba Cloud mapping |
The 2026-09-02 table above remains a historical snapshot. Prefer deepseek-v4-pro-0813 when you need the dated Pro ID; regional twins like deepseek-v4-pro-sg remain separate IDs.
Minimal call (OpenAI SDK)
from openai import OpenAI
import os

client = OpenAI(
    api_key=os.environ["NEXOROUTER_API_KEY"],
    base_url="https://api.nexorouter.com/v1",
)

r = client.chat.completions.create(
    model="deepseek-v4-flash-0731",  # or glm-5.3 / kimi-k3
    messages=[{"role": "user", "content": "In one sentence, what is an OpenAI-compatible gateway?"}],
)
print(r.choices[0].message.content)
Recommended steps:
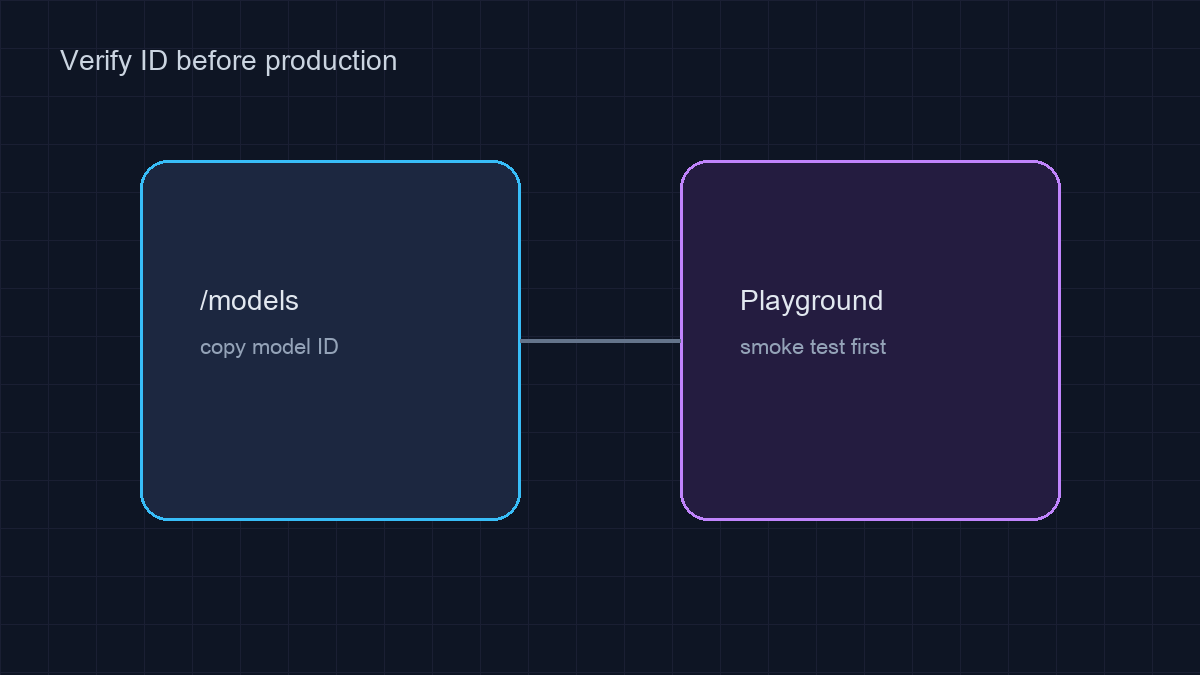
1. Open Models, search the ID, copy the exact string.
2. Smoke-test in Playground with a low max_tokens.
3. Follow first API call and choose models.
4. Check Usage Logs before raising concurrency.
Migration footguns
- DeepSeek: stop hard-coding
deepseek-chat/deepseek-reasoner(vendor retirement after 2026-07-24 15:59 UTC per DeepSeek V4 release notes). On NexoRouter prefer catalog IDs such asdeepseek-v4-flash-0731ordeepseek-v4-pro-0813. Regional twins likedeepseek-v4-pro-sgremain separate IDs. - GLM-5.1 vs GLM-5.3: the featured general chat ID
glm-5.1is not the same catalog row asglm-5.3. Keep announcement copy scoped to the ID you actually call. - GLM-5.3: on Z.ai’s API,
thinking.type: "disabled"fails. Fix that before swapping the model ID (see GLM-5.3 docs and the 14 Aug blog). - Kimi K3: thinking is always on; control effort with
reasoning_effort. In multi-turn, return the full assistant message (including reasoning when present).
NexoRouter documents public Chat Completions. Do not copy Responses tutorials or other contracts that are not yet in /docs.
Why this matters in LatAm
Teams in Mexico, Colombia, Chile, Argentina, or Brazil often keep a single OpenAI client. A gateway with ES locale, visible USD list prices, and a filterable directory lowers the cost of switching when DeepSeek, Z.ai, or Moonshot publish a new ID. Flow: official announcement → check /models → Playground smoke → production.
Official sources cited
1. DeepSeek-V4 Preview — 24 Apr 2026
2. DeepSeek API Change Log — 13 and 21 Aug 2026 entries
3. GLM-5.3 (Z.ai) — 14 Aug 2026
4. Kimi K3 Quickstart (Moonshot)
5. Moonshot AI — Kimi K3, 16 Jul 2026
Prices: live capture of nexorouter.com/models on 2 Sep 2026. Re-check the directory before budgeting.